#82: The First Step in a Data Architecture (Ingestion)
Mar 05, 2025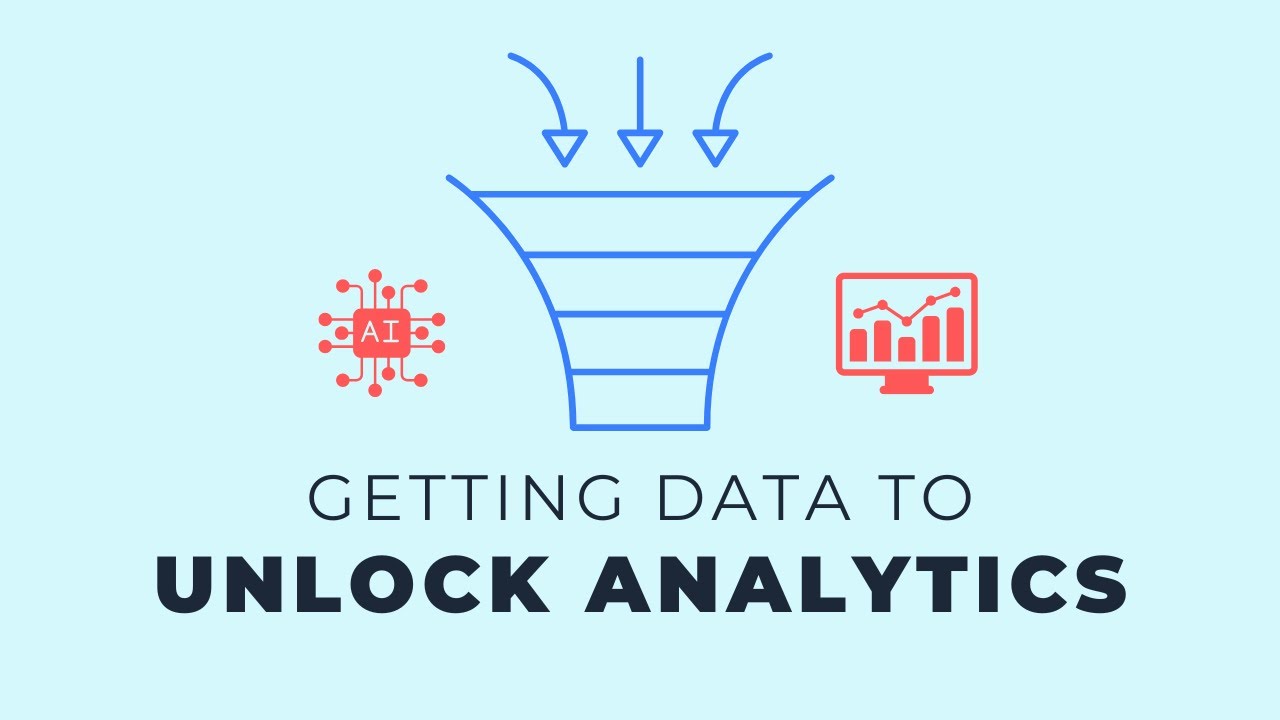
Data ingestion is the step that extracts raw data out of your source systems and loads it into one shared location, usually a data lake or a landing zone in your warehouse. It is the first piece of a data architecture because nothing downstream works without it. No reporting, no modeling, no machine learning, until the data is somewhere you can actually query it. The work used to be heavily custom and genuinely difficult, and today it is mostly plug and play through tools with prebuilt connectors. What is left to decide is which connectors you need, how a tool performs against your specific sources, how much customization you want to own, and how you name and organize the data once it arrives.
Key takeaways
- Data ingestion is extract and load: pull from the sources, land it in a data lake or landing zone, and leave transformation for later.
- Batch covers most teams. Prebuilt connectors move data on a schedule into a cloud database or file storage, and a custom Python script fills the gaps.
- Streaming and change data capture exist for the cases that genuinely need near real time, not as the default starting point.
- List your sources before you shortlist tools. Connector coverage is the constraint that decides most of these evaluations.
- No tool will have every connector you want. Expect to edge case around one or two, and pick knowing which ones.
- Run a proof of concept against your real sources. Performance and connector reliability depend on your setup, not on the vendor's marketing page.
- Decide your naming convention and your raw layout before the first load. This is where everyone on the team first touches the data.
What data ingestion is
Everyone wants to do the interesting things with their data. AI, machine learning, or in a lot of cases just basic reporting instead of a pile of Excel sheets.
None of it is possible until you can access that data from an analytics perspective, in one place, on your terms. Data ingestion is the component that makes that true.
The definition is narrow on purpose. Ingestion extracts raw source data and loads it into a data lake or a landing zone. It does not model, clean or reshape anything. That comes later.
Batch and streaming
How you implement it falls into two broad shapes:
- Batch. Data moves on a schedule. This is the most common form, and it usually means a tool with prebuilt connectors to your sources and to common destinations like a cloud database or file storage.
- Streaming. Data moves continuously, including change data capture, which reads a database's change log so inserts and updates show up in near real time.
Either way, the concept is the same. You are taking the sources and bringing them into a central hub so the business can consolidate and decide from one place.
Example tools
These are tools I have worked with. They are examples, not the full list, and the list changes every year.
Batch loading
- Fivetran. Managed, wide connector catalog.
- Stitch. Managed, similar category.
- Airbyte. Open source, with a cloud offering, and you can also host the open source version yourself.
Streaming and change data capture
- Apache Kafka. The common open source backbone for event streams.
- Amazon Kinesis. The AWS managed equivalent, with Azure and Google Cloud each offering their own versions.
- Debezium. Connects to databases and does change data capture off the transaction log.
Custom scripts
A custom Python script that extracts and loads is still data ingestion. It belongs on the same list as the managed tools, and for an odd source it is often the fastest path.
Three things to consider when you pick a tool
The hard part of this decision is not capability, it is that there are so many options that the choice gets overwhelming. Three criteria do most of the work.
1. Connector availability
Start by listing your sources. Write down every system you need to pull from before you look at a single vendor page.
What you will find is that one tool covers most of them and misses one or two that matter. It is unlikely you find one with every connector on your list.
That is fine, as long as you go in knowing which ones you will have to edge case around.
2. Performance
Performance depends on your sources, your destination and the rest of your architecture. Some tools simply work better against certain systems than others.
Connectors also drift. A source API changes, the connector changes with it, and you get errors you did not have last month.
Run trial loads and proofs of concept against your real sources. That is the only way to see which one behaves consistently for you.
3. Customization
This one ties back to connector availability. Some of your sources will not be available out of the box, so ask how much customizing you want to own.
Some tools let you build your own connectors. You can also write the extract and load yourself in Python and run it alongside the managed tool.
Weigh three things together: how much customization you need, how much you actually want to maintain, and what support the provider offers when it breaks.
Strategies for what happens after it lands
Picking the tool is only half of it. The other half is what you do with the data when it hits the landing zone.
Set a naming convention first
You have options. Prefix every object with the name of the source it came from, or drop the prefix and separate sources by schema instead.
Which one you pick matters less than picking one and staying consistent, rather than accepting whatever name the source hands you.
This is the first place people inside your company touch the data. The precedent you set here, clean and organized or scattered, trickles down into the rest of the platform.
Decide how raw data is laid out
You will have multiple sources, and multiple tables inside each source. Two layouts cover most teams loading straight into a database:
- Separate databases. One database for raw data and one for transformed data, with each source getting its own schema inside the raw database.
- One database, prefixed objects. Keep raw and transformed together, but prefix everything ingested so it groups on its own.
The prefix trick works because most databases sort objects alphabetically. Prefixing is what visually separates raw from modeled when you cannot separate them physically.
-- separate databases, one schema per source
raw.salesforce.accounts
raw.salesforce.opportunities
raw.stripe.charges

-- one database, ingested objects prefixed so they group together
analytics.raw_salesforce__accounts
analytics.raw_stripe__charges
Either way, someone new can open the database and tell within seconds what is raw and what the team built.
Where ingestion sits in the bigger picture
It is hard to have a good data architecture without the ingestion piece figured out, and it is still only one component of a much bigger process.
The two decisions worth slowing down for are the tool and the landing zone conventions. Both are cheap to get right at the start and expensive to redo once fifteen sources are loading every night.
If you want the companion pieces, I go deeper on the landing zone in Fix Your Data Pipeline From The Start, and on scoping the whole build in How to Build Modern Data Architectures Faster.
Key terms
Data ingestion
The architecture component that extracts raw data from source systems and loads it into a data lake or landing zone, with no transformation applied.
Landing zone
The place raw source data first lands inside your environment, before any modeling touches it.
Connector
A prebuilt integration between an ingestion tool and a specific source or destination, which is what makes modern ingestion closer to plug and play.
Change data capture
A streaming technique that reads a database's change log so inserts, updates and deletes flow into your platform continuously instead of on a schedule.
Raw database
A database dedicated to ingested data, usually split into one schema per source, kept separate from the database that holds transformed models.
Common questions
Is data ingestion the same as ETL?
Ingestion is the extract and load part. In a modern stack the transform happens afterward in the warehouse, usually with dbt, which is why people call the pattern ELT instead of ETL. The ingestion tool's job ends when the raw data is landed.
Should I build ingestion in Python or buy a tool?
Buy for the sources that have a good connector, build for the ones that do not. A managed tool removes maintenance you do not want to own, and a custom Python script is the right answer for an odd internal system. Most teams end up with both.
Do I need streaming ingestion?
Only if a business decision actually depends on data that is seconds old. Batch on a schedule covers the overwhelming majority of analytics work, and it is far simpler to operate. Add streaming for the specific use case that justifies it.
Should raw data land in a data lake or straight in the warehouse?
Both are valid landing zones. File storage is cheap and flexible for semi structured or high volume data, while loading straight into the warehouse keeps the path short when your sources are mostly databases and SaaS apps. Pick based on what your sources look like and what your transformation tool reads from easily.
What do I do about a source with no connector?
Check whether the tool supports building a custom connector, and if not, write the extract and load yourself. Keep it in the same landing zone and the same naming convention as everything else so it does not become a special case downstream.
How often should ingestion run?
Match it to how often the data is used, not to how often it changes. A daily report does not need hourly loads, and loading more frequently than anyone looks mostly adds cost and failure surface.
Related reading
- Fix Your Data Pipeline...From The Start
- How to Build Modern Data Architectures Faster
- How to Create a 3 Layer Data Model Pipeline
- Data Architecture w/ dbt (Putting It All Together)
Final takeaway
Every architecture I have helped a team stand up started here, because until the data is in one place nothing else is on the table. Pick the tool on connector coverage, prove it against your real sources, and spend an hour on naming before the first load lands.
Additional Free Resources
Starter Guides & Checklists
Explore additional free resources built on the same patterns I use with real clients so you can build your own with structure and confidence. Topics include data architecture, modeling and more specifically for small data teams.